Showing posts with label RDF. Show all posts

Thursday, 23 July 2015

Semantic Web for the Working Ontologist: Chapter 13


After all last week's, er, 'excitement', it's back to my attempt to grasp the theory of data modelling, RDF and its various iterations, OWL and associated concepts.

First off, I need to say there's something in chapter 13 – title: Ontologies on the Web—putting it all together – that I really don't get, and that's the use, in the section on Dimension checking in QUDT (the acronym for a specific ontology: Quantities, Units, Dimensions, Types) of vectors as a way of representing signatures for compound quantities.

When I say I don't get it – I understand the principle, that "QUDT defines eight basic quantities", including "length, time and mass", and that the process of dimensional analysis requires that units used to measure compound quantities require a signature showing how the … Oh…

Hang on … what I was going to say here was that I didn't understand how the vectors providing the signature for how these compound quantities are comprised from the eight basic quantities/units are calculated. Why, say, if "we write our vectors in the order [length, mass, time] then the vector for velocity is [1, 0, -1]", even though the authors explain how "the magnitude of the vector in that component begin the exponent of the the base quantity in the formula for the compound quantity".

I'd read that page at least four times before giving up. But it's just this second clicked. The vector for velocity is [1, 0, -1] because velocity = length/time. The zero's there because mass isn't a factor. Duh. Remarkably, I did pass maths A level. But only just, and with a lot of tutoring. And it was a loooooong time ago now…

Chapter 13 introduces and outlines the uses of three online ontologies: QUDT, Good Relations and ChEBI – Chemical Entities of Biological Use – which "is published as part of the Open Biological and Biomedical Ontologies Foundry (OBO)".

Developed by NASA, "the goals of QUDT are to provide
  1. A standardized consistent vocabulary, focused on terminology used in science and engineering.
  2. A set of consistent coded identifiers, for human and machine use.
    1. nd machines, avoiding problems with uncertainty and misinterpretation.
  3. A collection of foundational vocabularies that can serve a variety of applications.
  4. A framework designed for extensibility and evolution, but model-based (instead of just a typical dictionary) and governed."
Outside of engineering, it's widely used for online currency conversion.

The Good Relations ontology is used for commerce. It provides search engines with rich information about products and services, enabling them to assess the relevance of the the product or service to the "location, time, identity, profile, and preferences of the person behind the query" (from GoodRelations).The authors provide an example of how it can be used by a nail bar that also offers massages, both to publicise its services and to enable browsers to work out which service, provided by comparable beauty salons, offers the best value massage per minute.

And CheBI is
"a freely available dictionary of molecular entities focused on ‘small’ chemical compounds. The term ‘molecular entity’ refers to any constitutionally or isotopically distinct atom, molecule, ion, ion pair, radical, radical ion, complex, conformer, etc., identifiable as a separately distinguishable entity. The molecular entities in question are either products of nature or synthetic products used to intervene in the processes of living organisms." (from the ChEBI website)

Incidentally the ChEBI website features an "Entity of the Month". At the time of writing it's butyl anthranilate, a naturally occurring substance that scientists are currently testing as a safe insect repellent to protect fruit – and, potentially, people – from being eaten/bitten by flying insects…
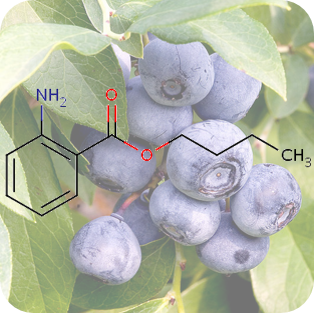
ChEBI's Entity of the Month for July 2015. And some blueberries.
The authors also introduce the term owl:imports which allows one ontology to refer explicitly to another, and enables inferences to be drawn from the imported ontology within the ontology into which it has been imported.

That's it for this week. And, just so you know, there are three, short chapters to go…

Thursday, 25 June 2015

Semantic Web for the Working Ontologist: chapter 11

Because I've enjoyed leaving everyone on tenterhooks after the cliffhanger at the end of chapter 10, and to prolong the joy, from now on, I'm going to alternate blogging a chapter of this book every fortnight, with musing on other subjects*

Anyway, this week's chapter covers basic OWL, and focuses on the use of owl:Restriction, which the authors tell us – almost breathless with excitement – "opens up whole new vistas in modeling capabilities".

In OWL, a Restriction is a special type of class: one that's defined "by describing the individuals it contains… in terms of existing properties and classes".

The chapter focuses on three kinds of restrictions:
owl:allValuesFrom – all values from a set of properties must apply
owl:someValuesFrom – one or more values from a set of properties apply
owl:hasValue – refers to a particular value for a property.

There's a difference between the first two of these which is subtle and not immediately obvious. someValuesFrom "is defined as a restriction class such that there is at least one member of a class with a particular property". That means that "there must be such a member". allValuesFrom, however, "means 'if there are any members, then they all must have this property", which doesn't "imply that there are any members". This will, apparently, be important later in the book (there are, gentle reader, still 5 chapters to go). Oh, and these three restrictions are often shortened to the keywords all, some, and value, using the Manchester Syntax (developed at the University of Manchester).

Because it's so useful and frequently-used, owl:hasValue – the type of restriction that "effectively turns specific instance descriptions into class descriptions"  – is "identified in the OWL standard in its own right". It is viewed "as a design pattern" and given a name: the Class-Individual Mirror pattern. It is used to describe "the relationship of an individual to a set—this is the set of all things that relate to this individual in a certain way."

Having demonstrated the application of restrictions in the design of a questionnaire, the authors go on to explore ways of ensuring steak isn't classified as a vegetarian food, and preventing a steak-eater from being described as a vegetarian, and, then, to explore 'relationship transfer'. Relationship transfer happens when "Everything related to A by property p should also be related to B but by property q".

not suitable for vegetarians
So, for instance, everyone who has bought an NUS Extra Card† will also be a student affiliated to an educational institution (or a work-based apprentice - but let's not split hairs here). Or, as in the authors' examples "'Everyone who plays for the All Star team is governed by the league's contract' and "Every work in the Collected Works of Shakespeare was written by Shakespeare'".

Finally, they describe the difference between rdfs:subClassOf and owl:equivalentClass. The former is "a simple IF/THEN relation", the latter "an IF and only IF relation". In other words, it is two IF/THEN relations: "one going each way".

And, in their summary, Dean Allemang and Jim Hendler explain the importance of restrictions. Essentially, "they can be used to model complex relationships between properties, classes, and individuals". This means that "interactions of multiple specifications can be understood and even processed automatically." And, while our brains are busy working out the possibilities that opens up, I'll finish by saying that next week I'll be blogging/thinking more about reader journeys.

I also won't make the mistake I made this week of blogging on 2 computers and accidentally overwriting the finished version by saving an earlier draft and having to rewrite. Grrrrr.

* oh, all right, it's mostly because I'm very busy at the moment, and this allows me to blog about some of the stuff I'm doing

† and if you're eligible and haven't, it's well worth it

Thursday, 4 June 2015

Semantic Web for the Working Ontologist: chapter 9

This week we're on to "Using RDF-Plus in the wild", where the authors introduce us to two real-world applications of the principles and practices explained in chapters 1-8.

Both "are about setting up an infrastructure for a particular web community". Data,gov, the US government project to put public information online in machine-readable form and FOAF – the acronym for Friend of a Friend, which is "a machine-readable ontology describing persons, their activities and their relations to other people and objects." (quote from Wikipedia).

 The subset of US government data the authors focus in on is the list of cases "about alleged violations of Title VIII of the Fair Housing Act" filed with the Office of Fair Housing/Equal Opportunity (FHEO). The original data gives a case number, and a list of possible reasons for the complaint – each of which is marked with either a 0 or a 1, to indicate whether or not it is the basis of the complaint –  as well as the county that the omplaint is filed in/relates to. The authors take us through ways of using RDFS and SPARQL to organise and process this data to make it more meaningful and useful, enabling human beings to work out where, for instance, alleged violations of Title VIII of the Fair Housing Act cluster, and which reasons form the basis of the most cases.

FOAF – started in 2000 – "began with a simple observation"
If we are to support social networks on the Web, individuals must be able to take control of their own data, host it as they please, manage it using whatever tools they please, but still interact with other users, regardless of the choices these other users make. (p196)
This, more than Data.gov, demonstrates the adaptability of RDF, SPARQL and their associated languages, standards, frameworks, technologies – or however they should be described.

What's key is that "because Anyone can say Anything about Any topic, FOAF allows anyone to make novel statements about people, projects, and so on and to relate these statements to other statements already made."

Everything, in other words, can be connected to everything else, but by machines, and in ways that, ultimately, make sense to humans.

I think my inner hippie is showing…

My inner hippie. Yup. That's what I'm like on the inside.


Thursday, 21 May 2015

Semantic Web for the Working Ontologist: chapter 7

I am now much, much further into a technical book than I've ever been before in my life. That feels like an achievement: even if I don't come away from this with any more than a fragmentary grasp of all things RDF and beyond…

So – this week's chapter is concerned with RDF Schema. It is all about sets which, somehow, feels more comfortable and intuitive than all the RDF graphs, even though I've forgotten all the mathematical set-related signs (a very long time ago I did a pure maths with stats A level very badly). It explores the following questions. "Which individuals are related to one another and how? How are the properties we use to define our individuals related to other sets of individuals and, indeed to one another?"And it answers the question of how to express those relationships in a way that allows inferred triples to be constructed from asserted triples.

And "schema"? The term schema was, according to Oxford Dictionaries, coined in the 18th century. It's derived from the Greek "skhÄ“ma … [meaning] …'form, figure'", and the definitions the dictionary provides are
1. technical A representation of a plan or theory in the form of an outline or model:
2. Logic A syllogistic figure.
3. (In Kantian philosophy) a conception of what is common to all members of a class; a general or essential type or form. 

Or, in RDFS, according to Allemang and Hendler,  "The schema is information about the data." It is information about information. "The key idea of the schema in RDF", they continue, "is that it should help provide some sense of meaning to the data."

It does this "by specifying semantics using inference patterns". Which means that it expresses relationships in triples, using defined terms. So "the basic construct for specifying a set in RDFS is called an rdfs:Class. So for a subject say :FloweringPlant you'd have the predicate rdf:type and the object rdfs:Class. There's also rdfs:subClassOf, and, importantly – because it can include verbs as well as nouns – rdfs:subPropertyOf.

"In general, rdfs:subPropertyOf allows a modeler to describe a hierarchy of related properties". The more specific a property, the lower down the hierarchy it sits; the more general, the higher up. So, "whenever any property in the tree holds between two entities, so does every property above it". In other words, if entity 1 is the subproperty of entity 2 above it, it must also be a subproperty of entities 3 - n above entity 2. And we only need to assert the first relationship in a triple for the rest to be inferred.

"RDFS," say the authors, "'extends' RDF by introducing a set of distinguished resources into the language." I'm assuming that they're using "distinguished" to mean "distinct", rather than either "Very successful, authoritative, and commanding great respect" or "Dignified and noble in appearance or manner" (Oxford Dictionaries again). But what do I know?


Apparently this is an image of "Distinguished Gentleman's Ride London". Glossing over any issues with the word "gentleman" for the purposes of this caption, it's possible there may be something I don't understand about the word "distinguished".
Meanwhile, back in the book I'm supposed to be getting my head round, the authors are introducing the other key concepts for this chapter: rdfs:domain and rdfs:range. These describe a property "that determines class membership of individuals related by that property".

In the margin of p130 (for this, dear reader, is how far we have come), I've scrawled in big pencilled caps REREAD THIS, as I evidently failed to understand it first time round. This time it seems fairly clear. Essentially the use of the terms "domain" and "range" is inspired by their use in maths, where "the domain of a function is the set of values for which it is defined, and the range is the set of values it can take." In RDFS, "A property P can have an rdfs:domain and/or an rdfs:range." And the two terms provide information on how a "P"is to be used: "domain refers to the subject of any triple that uses P as its predicate, and range refers to the object of any such triple".

EDIT 28/05/2015. After reading this blog, Paul Rissen provided the following, much improved explanation for domain and range


It's also significant that there's no way in RDF to say that something isn't a member of a particular class: this means that "there is no notion of an incorrect or inconsistent inference". So modelers have to be careful in defining set relationships.

Most of the rest of this chapter is concerned with application of these concepts/terminologies, to show, for instance, how you can relate entities by using triples to define them as subsets of one another: doing this both ways ensures that an item defined as a subset of one will automatically be considered a subset of the other, or if they're related, but not hierarchically to each other, by creating another entity (or set) that sits higher up the hierarchy and that they original two entities are subsets of.

Conceptually it's comparatively easy – applied IRL situations, I imagine, requires a lot of careful thought.

Next week… RDFS-Plus. So I guess that'll be like this week, only more so…


Thursday, 23 April 2015

Semantic Web for the Working Ontologist: chapter 3

Now I'm onto "RDF—The Basis of the Semantic Web"

It's when it starts getting down to this sort of nitty-gritty stuff and I have to internalise new meanings for familiar (or semi-familiar) words that I feel in need of intellectual flotation aids. But I'm gonna dive straight in and hope to avoid a belly flop and every other variety of lousy extended metaphor.

Chapter 3 starts with an explanation of what RDF – the Resource Description Framework – is for, which is "managing distributed data", so that anyone can be able not only "to make a statement about any entity", but also to "specify any property of an entity". An "entity" is known, in this context, as a resource.

RDF is designed to enable that to happen by setting rules for how the properties of an entity are defined/expressed. These are in three parts, called a "triple" and follow the form subject – predicate – object, where the predicate is the quality linking subject and object. This framework allows for numerous ways to describe a resource/entity.

But this practice is only effective if entities have an agreed Uniform Resource Identifier (URI): "(which specifies things like server name, protocol, port number, file name etc) to locate a file (or a location in a file) on the Web". This "provides a global identification for a resource that is common across the web".

Ok - think I'm still hanging on in here. URIs tend to be long, so conventions have evolved for abbreviating them in print. The one the authors are using is called qnames.

Qnames have two parts - a "namespace" and an "identifier", (written Namespace:Identifier).
The namespace signifies what type of thing the identifier is; the identifier specifies the entity's, well, identity. Each part of each triple has its own qname, so that the different properties of a resource can be combined in different ways. So, in the RDF table the authors provide titled "Geographical Information as Qnames", one row is

geo:Scotland     geo:PartOf   geo:UK

And, in the following table, titled "Triples Referring to URIs with a Variety of Namespaces", we find entries including

lit:Shakespeare          lit:wrote          lit:KingLear
bio:AnneHathaway   bio:married     lit:Shakespeare

and

lit:Shakespeare         bio:livedIn     geo:Stratford

For these to work, there need to be a range of standardised namespaces, so these have been specified by W3C. Incidentally, it's a complete coincidence that all these references to Shakespeare are appearing in a blog published on his birthday.

The authors discuss one – rdf:type – at some length. "rdf" indicates that "type" (which translates into human English as "is an instance of") is an identifier used in RDF (resource description framework), rather than in RDFS (the RDF Schema language) or OWL (the Web Ontology Language).

I managed to follow that. But now, we're on to "higher-order relationships", where, for instance, we want to say that someone says something about something. The example the authors give is "Wikipedia says Shakespeare wrote Hamlet".

While we can, as the authors show, express the statement "Shakespeare wrote Hamlet in 1601" in three triples:

"bio:n1       bio:author                  lit:Shakespeare .
 bio:n1        bio:title                      "Hamlet" .
 bio:n1        bio:publicationDate   1601" .
saying that Wikipedia says Shakespeare wrote Hamlet requires a whole other layer of information, rendered here as
"q:n1  rdf:subject  lit:Shakespeare ;
           rdf:predicate  lit:wrote ;
           rdf:object  lit:Hamlet .

web:Wikipedia m:says q:n1 ."
The authors suggest readers notice that the "reification triple" doesn't necessarily mean that Shakespeare did write Hamlet, just that Wikipedia says he did.

What I noticed is that I am being gently introduced to some coding conventions.Things like q:n1, that are dropped in without explanation. And the space before the ".". This is explained a page or so later, during the discussion of "alternatives for serialization", including N-Triples – which refer "to resources using their fully unabbreviated URIs", making them difficult to print on paper – and Turtle: the method used in the rest of the book.

Turtle uses qnames, so before using it to express triples, each (local) qname needs to be linked to its (global) URI, using the form

"#prefix rdf: http//www.w3.org/1999/02/22-rdf-syntax-ns#"

Although I'm slightly confused, as above that is an example from an earlier illustration in the book:

"#prefix mfg:
<http://www.WorkingOntologist.com/Examples/Chapter3/Manufacturing#> (the link doesn't work, btw).

So I'm not clear whether we need the < & > as in HTML coding, or not… Anyone care to enlighten me?

Nearly at the end of the chapter - just a few more things I need to remember before I attempt chapter 4: "Semantic Web application architecture" (urk!).

1. Turtle uses contractions/abbreviations so that
a. when several triples share both subject and predicate, they can be represented economically. For example
lit:Shakespeare b:hasChild b:Susanna .
lit:Shakespeare b:hasChild b:Judith .
lit:Shakespeare b:hasChild b:Hamnet .
can be boiled down to
 lit:Shakespeare b:hasChild b:Susanna, b:Judith, b:Hamnet .
Or, to represent an ordered list (birth order, in this case)
 lit:Shakespeare b:hasChild (b:Susanna b:Judith b:Hamnet) . 
b. rdf:type is usually abbreviated to "a", so
lit:Shakespeare a lit:Playwright
rather than
lit:Shakespeare  rdf:type  lit:Playwright .
 The authors then quickly refer to RDF/XML - a method of representing RDF serialisations for the web, and also to "blank nodes", which allow for the representation of resources with no Web identity. They give the example of Shakespeare's mistress, the inspiration for sonnet 78 (at which point I got distracted and went off to read about poetry, as that sonnet was inspired by a young man – most likely Henry Wriothesley or William Herbert – not a woman). I will probably regret that by half way through chapter 4, but heigh-ho.

Anyway, "if we don't want to have an identifier for the mistress … RDF allows for a "blank node" or bnode for short" which "is indicated by putting all the triples of which it is a subject between square brackets as in
[ rdf:type bio:Woman;
        bio:livedIn  geo:England ]
Or, as it should be
 [ rdf:type bio:Man;
        bio:livedIn  geo:England ]
 And that's it for chapter 3. If I hadn't made a commitment to blog my way through this book, I'd probably have given up already…


 That's me, that is.

Wish me luck for chapter 4…

Thursday, 16 April 2015

Semantic Web for the Working Ontologist: chapter 2

Chapter 2 is titled "Semantic modelling".

It explains that models are intellectual tools designed to "help people understand their world by forming an abstract description that hides certain details while illuminating others." In other words, the key to an effective model is working out which details to illuminate and which to conceal.

Models help with communication, explanation and prediction. They also "mediate among multiple viewpoints", by making commonalities explicit and enabling discussion about differences.


There's then a discussion of community tagging as a method of document modelling, with the caveat that as more people provide content, popular tags "saturate with a wide variety of content, making them less and less useful" for people trying to identify something specific.

According to the authors (and this is a key point):
This sort of problem is inherent in information modeling systems; since there isn't an objective description of the meaning of a symbol outside the context of the provider and consumer of the symbol, the communication power of that symbol degrades as it is used in more and more contexts. (p16)
To extrapolate, this is why Semantic Web standards require "modeling formalisms": so that there's an "objective description of the meaning of a symbol" that can exist "outside the context of the provider and consumer of the symbol".

Semantic Web standards follow a similar idea of class hierarchies "for representing commonality and variability" to Object-Oriented Programming. "High-level classes represent commonality among a large variety of entities, whereas lower-level classes represent commonality among a small, specific set of things." Which, I guess, means that lower-level classes are subsets of higher-level classes.

But what we need to add to that is the idea that "any model can be built up from contributions from multiple sources". And these multiple sources may well use different symbols to signify the same thing – or the same symbol to signify different things.

At this stage in the Semantic Web's development, it's often not possible to make a decision about which symbol representing something should be chosen as the symbol (the authors use the example of Pluto's astronomical and astrological symbols). But it should be possible to agree that each entity should be represented by only one symbol. So, in this instance "a model can provide a framework for describing what sorts of things we can say about something".

The chapter concludes with a list of Semantic Web languages from least -> most expressive: with the caveat that more expressive models are not necessarily better than less expressive models. To illustrate this, they show 3 different ways of "expressing" a water molecule, from the formula H2O, through H–––––O–––––H (showing how the components are joined) to a drawing that shows the relative sizes of the components and how they are positioned in relation to each other. Each is useful in a different situation.

The three Semantic Web modeling languages are:
RDF – the Resource Descripton Framework
RDFS – The RDF Schema Language
and
OWL

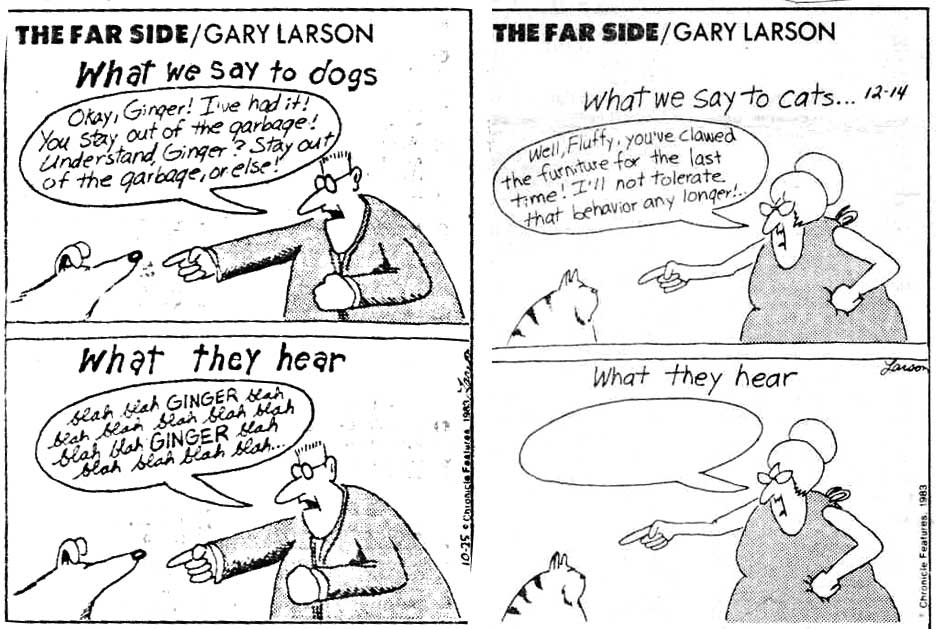
The next few chapters introduce these languages. And this, I suspect, is where I'll start to become unstuck. Usually, with technical books, I'm fine with the concepts. But when I start having to actually get to grips with the nuts & bolts of languages I turn into the dog in that Far Side cartoon:


Still, at least I'm not quite the cat… At least I hope I'm not… Will let you know in next week's installment…